Data Scraping
Web scraping services that hand you clean data
Downloading the pages is the easy half. Our web scraping services cover the other half too. The software we build collects data from publicly accessible websites and documents, cleans it, classifies it with AI and delivers it in the format you already use.
Data Scraping
Sample scenario
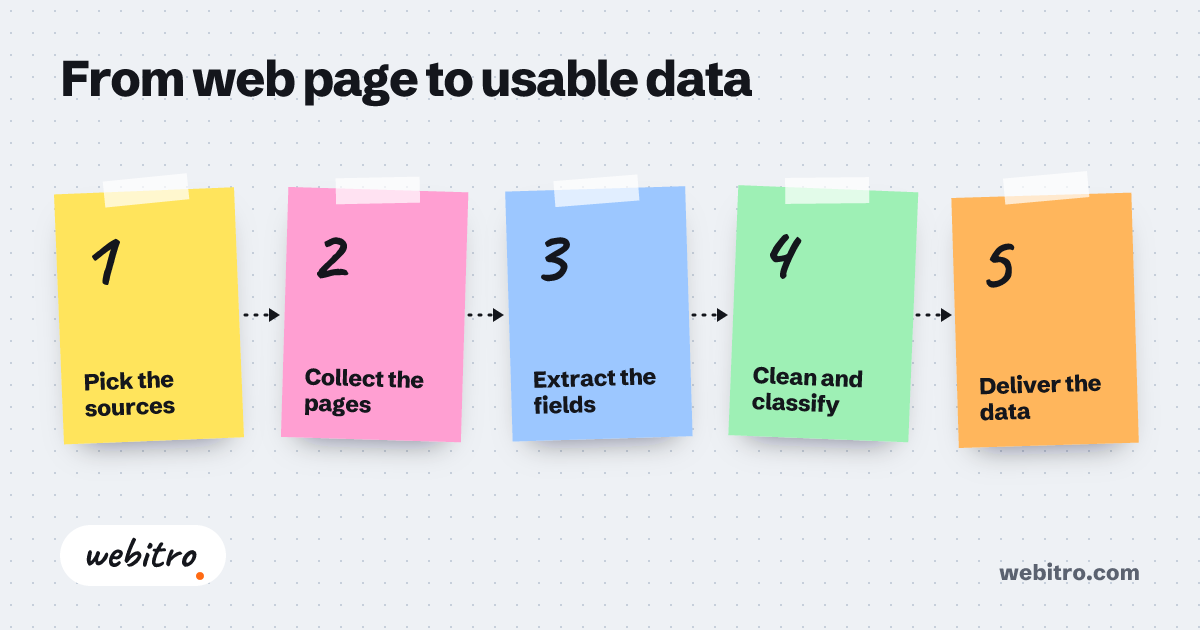
From web page to usable data
- 1Pick the sources
- 2Collect the pages
- 3Extract the fields
- 4Clean and classify
- 5Deliver the data
What we build
The request usually fits in one sentence: “I want to see my competitors’ prices every morning.” The work behind it is software that runs on a schedule and tells you when something breaks.
- Price and stock tracking: records the price and availability of products on the sites you name, at regular intervals.
- Catalogue collection: brings product names, specifications and images from supplier sites into one table.
- Notice monitoring: alerts you when a new tender, job advert or official announcement is published.
- Document reading: turns tables and text in PDFs and similar files into structured data.
- Review and news digests: groups public reviews and articles by topic.
How the collection works
The software visits the chosen pages in order, extracts the fields you need and stores them. It spaces out its requests so it does not strain the site. On each run it updates only the records that changed.
Websites get redesigned. When that happens a scraper starts returning empty or wrong values. So we put checks on every source. If the price field comes back blank, or the number of records suddenly drops, the system raises an alert.
Where AI for web scraping earns its place
Raw data is messy. The same product is “1 l” on one site and “1000 ml” on another. Category names do not match and addresses come in every format. This is the part we give to AI: it normalises units, matches the same product across sites and sorts text into your own categories.
A model can be wrong. Fields that must be exact, such as prices, are extracted by fixed rules. Where the model does decide, we check samples regularly and flag the records it was unsure about.
What we will not collect
We work only with publicly accessible data. We do not enter password-protected areas or get around security measures. We read the site’s terms of use and its robots rules. If a source does not allow collection, we tell you and look at permitted options such as an official API or a licensed feed.
Personal data is a separate matter. Being public does not make information free to process. For anything that falls under the GDPR or Turkey’s KVKK, we discuss the purpose and the legal basis first.
How the data reaches you
You choose: an Excel or CSV file, direct writes into your own database, or an API your existing software can call whenever it needs fresh data. For small teams we can also build a simple screen to browse the results.
The system runs on your server, on your computer or in the cloud. The collected data stays with you.
How a project runs
We start by listening and writing down the sources and fields with you. Then we design the flow, and no code is written until you approve the design. After development we hand over a working system. Technical support continues around the clock after delivery, which matters here because source websites keep changing.
Frequently asked questions
Is web scraping legal?
It depends on what is collected and how. Gathering public, non-personal data within a site’s terms is a different thing from entering protected areas or processing personal data without a basis. We assess every source on those points. For a firm legal opinion, ask a lawyer.
What decides the price of a scraping project?
The number of sources, how the sites are built, how often the data is refreshed, the amount of cleaning and classification and the delivery format. The AI model and the server add usage costs. We do not publish a fixed price list. We listen to what you need and send an itemised quote.
Can off-the-shelf AI web scraping tools do the same job?
For a one-off export from a few pages, often yes, and we will say so. Ready-made AI web scraping tools become harder to live with when you need many sources, a fixed schedule, checks on data quality and a connection to your own systems. That is where custom software fits better.
What happens when a website changes its layout?
The scraper starts returning bad values for that source and the checks catch it. You receive an alert, and we update the extraction rules for the new layout.
How often can the data be updated?
As often as the source reasonably allows. Many projects run once a day. We set the interval so the data stays current without burdening the site.
Related article
AI for web scraping: what it changes and what stays the same
AI for web scraping makes extraction and cleaning easier, but the hard parts remain. A plain guide to the tools, the limits and the rules that still apply.